
How do you get consistent operational reviews across 1,000+ locations without adding headcount?
Run consistent operational reviews across hundreds of locations without adding headcount. Capture your best operator’s judgment and apply it every cycle.
Meta title (54 characters): Consistent Operational Reviews Across 1,000+ Locations
Meta description (153 characters): Run consistent operational reviews across hundreds of locations without adding headcount. Capture your best operator’s judgment and apply it every cycle.
Focus Keyword: operational reviews
How do you get consistent operational reviews across 1,000+ locations without adding headcount?
By the Scoop team
You get consistent operational reviews across 1,000+ locations by capturing how your best operator judges a location and running that same judgment against every location, every cycle. Hiring more reviewers spreads the inconsistency wider, and better dashboards still wait for someone to open them.
The bottleneck is not data, it is distributing judgment.
We run this as a managed service. We run the review every cycle, your BI stack and dashboards stay exactly where they are, and your managers keep every decision.
Our co-founder Neil Shepherd describes what a good COO-level review sounds like:
"Here's what the COO found. Here's what you need to do to correct this adverse trend."
The problem is that this review almost never reaches the frontline with the same quality.
The data exists.
The reports exist.
The same standard of judgment.
Applied to every location.
What makes consistent operational reviews hard at scale?
Review quality drops every time it moves one level down the chain. The COO knows what to look for. By the time that standard passes through regional VPs, district managers, and store managers, every location is getting a different version of it.
The frontline reality makes it worse. Many store and unit managers are new to the role or simply stretched too thin, so performance varies widely from location to location, and the COO owns that variation.
Run the math
A typical district runs about 12 stores, so a 1,000-location operator needs more than 80 district managers. That is a span of control problem, and it compounds at every layer:
Weekly visits go to the stores in trouble: The severe ones get the attention.
The middle of the pack gets a glance: Check-ins happen less often.
Store managers stay on the floor: They are hired to run people and shifts, not to work through a stack of BI reports.
When operational reviews across hundreds of locations depend on each reviewer's time and experience, the review varies with the reviewer.
Why do two locations with the same numbers get different reviews?
Because the number is a symptom, and the cause can be several different things.
Two reviewers looking at the same sales decline often reach two different conclusions. One may not look at all.
A veteran retail operations consultant we work with, who spent years running store chains, put it this way:
"When you look at the sales number, sales number is the symptom."
It is a lagging indicator of whatever happened to get you there. Here is a concrete case from supermarkets:
Same chain, same pricing, same promotions, same layout: Two stores that look identical on paper.
Store one replenishes shelves immediately: Nothing sits empty.
Store two takes its time: Items sit empty, and sales leak out.
On a sales report, the second store is simply "down." The question that finds the cause is simple:
Why are total sales healthy in both stores while specific categories run much lower in one? Usually, because the shelves were not replenished.
Here is how that same headline plays out with 3 reviewers:
District manager A sees sales down 6%, splits it by category, connects the gaps to replenishment timing, and coaches the overnight shift.
District manager B sees sales down 6% and asks for a stronger promotion next month.
District manager C has eleven other stores, two of them red. This one does not get reviewed this cycle.
Our five-step check on why a store is down lays out a simple version of this diagnostic. The steps are not hard. Running them on every store, every cycle, is where the stores costing you margin slip through.
Why do district managers miss the same locations cycle after cycle?
Because attention follows the alerts, and a healthy total hides a weakening category.
A store at plan overall gets a green light even if one category has slipped for three straight months, propped up by a promotion somewhere else. That slow slide is the drift problem.
The second reason is volume. The same consultant warned that reporting on 45 things creates analysis paralysis: "How are you going to look at 45 reports?" Some managers perform worse because the reports eat the time they should spend running the store.
That is the pattern behind why dashboards don't work for multi-location operators. Then there is the reporting chain itself. At one retail chain we work with, the cycle looked like this:
Friday: every district manager writes a report on their stores.
Saturday morning: every regional VP reads all of those reports, then writes their own. The internal name for it is the Saturday report.
The result: the regional VPs lose their weekend mornings, and the quality of each review still depends on who wrote it.
"The regional VPs want their Saturday mornings back." Neil Shepherd
Why doesn't adding headcount fix it?
Because more reviewers means more interpretations, not more consistency.
Every new district manager brings their own standard, and it takes time to learn what your best operator sees in a single glance.
The volume is also bigger than any team can cover. Scoop can run 50 or 60 individual analyses on a single location, each chosen based on what the previous one found. Across 1,000 locations, that is 50,000 to 60,000 lines of inquiry every cycle.
A person reading a sales report may spot one or two things. They will not see the 25 or 30 factors behind the story. Here is what adding people buys:
Wider variation: Each new reviewer applies a slightly different standard.
A long ramp: The tribal knowledge that makes your best operator good is not written down for a new hire to read.
The same blind spots: People still review the red stores first and the quiet decliners last.
Key-person risk: When that judgment lives in one COO's head, operational knowledge loss is one resignation away.
Headcount scales capacity. It does not scale judgment.
How do you review every location without adding reviewers?
You capture the judgment once and run it everywhere. That is the core of AI performance management: your best operator's review becomes the standard, and every location gets it every cycle, whether or not it is flagged.
The COO codifies how they want the business run, that logic is coupled with analytics, and the result goes in front of every frontline manager.
Capture works like a tape recorder: record everything your best operator thinks as they read their BI reports, then let the system do that on their behalf.
Our team runs that capture, not yours, from interviewing your managers and codifying how they like doing things to repeating the review every cycle. Here is how it works once the judgment is captured:
Screening: Every location is checked against the operator's criteria: year-over-year deviations, balance between related metrics, early warning signals.
Investigation: When a screen trips, an investigation opens and drills further based on what each finding shows.
Root cause: Machine learning tests 10 to 20 variables at once against a healthier prior period, catching patterns a two-dimensional drill misses.
Synthesis: Findings are read through the operator's captured logic, then rolled up from store to district to region to the executive view.
A general-purpose AI model knows nothing about how your business runs. The captured judgment is what keeps every investigation on the route your best operator would take.
What arrives at each location every cycle?
A briefing, not a dashboard.
Each manager receives what changed, why it changed, and what to do next, with the evidence behind every conclusion. Nobody logs in or builds a query.
We run the review every cycle: It is a managed service. Nobody on your team sets it up, triggers it, or maintains it.
You keep everything you have: Your BI stack, dashboards, and reporting stay in place. We add the diagnostic and action layer on top.
Each role gets its own view: The store manager sees the full investigation, the district manager sees which stores need attention first, and the COO sees what is systemic.
Managers keep every decision: For the Saturday report, we draft the summary and the regional VP edits and approves it.
A regional VP should be able to say exactly what happened in the region: these stores are doing well, this one is not, and here is why. A pricing change, a new competitor, or a couple of people out sick, so the floor was not fully covered.
That is what a consistent read on every unit looks like. Most engagements start with a pilot in one or two districts, and the implementation path runs from connecting data to a working pilot in weeks.
Frequently asked questions about consistent operational reviews on multi-location businesses
What is an operational review at the location level?
An operational review at the location level is a structured check of one location's performance against a defined standard, run every cycle. It answers what moved, why it moved, and what the manager should do about it. Unlike the spot-check model most multi-location operations run, it covers every location, not only the flagged ones.
How is this different from a BI dashboard or alert system?
A dashboard shows the numbers and waits for someone to interpret them. An alert flags when a metric crosses a threshold, which helps with anomaly detection but does not explain the cause. A location review investigates why the number moved and recommends a next step using your best operator's judgment, and it runs on top of your existing BI stack rather than replacing it.
What does a location briefing actually contain?
A location briefing compares the location against its peers and its own history, then names the few issues that matter most this cycle. Each issue comes with its likely driver, the supporting evidence, and specific actions for the manager. Later cycles check whether those actions worked, which is how retail drift gets caught before it reaches the P&L.
How do you scale this without it becoming noise?
You keep the headline set small and rank everything underneath it. Experienced retail operators often manage from 6 to 10 core KPIs instead of 45 reports, while the review still combs through the 50 or 60 analyses behind them. Severity ratings put critical locations first, so a performance management layer for distributed businesses surfaces only the handful of issues worth acting on this cycle.
Get insights like this every week
Analytics, ops strategy, and product updates. No noise.
Keep reading
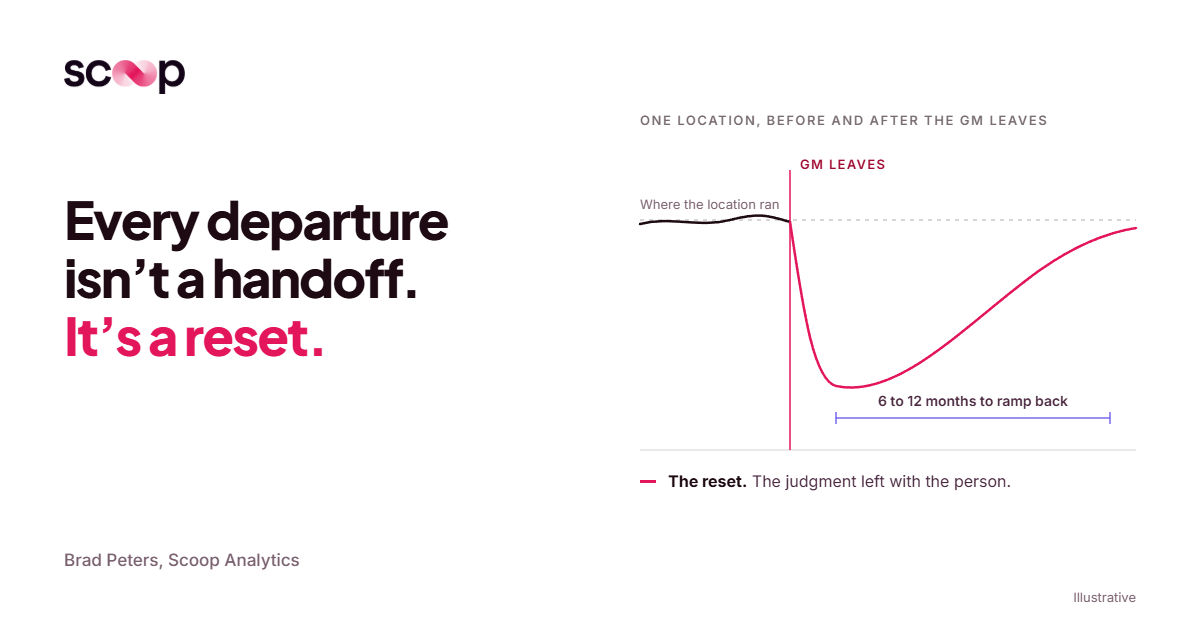
Why Multi-Location Businesses Lose Operational Knowledge Every Time Someone Leaves
The Best Retail AI Platforms for Multi-Location Operations
What Is Tribal Knowledge in Multi-Location Operations?
Book a discovery call
Reach out to start a two-way conversation about your industry, your performance variations across locations, and whether Scoop is the right fit for you.